Appendix D — Regular Expression Reference
This appendix provides a comprehensive reference for regular expression (regex) patterns used in text processing with tools like grep, sed, awk, and R. The tutorial treatment is in Chapter 9.
D.1 Basic Metacharacters
| Character | Meaning | Example | Matches |
|---|---|---|---|
. |
Any single character | a.c |
“abc”, “a1c”, “a-c” |
* |
Zero or more of preceding | ab*c |
“ac”, “abc”, “abbc” |
+ |
One or more of preceding | ab+c |
“abc”, “abbc” (not “ac”) |
? |
Zero or one of preceding | colou?r |
“color”, “colour” |
^ |
Start of line | ^The |
Lines starting with “The” |
$ |
End of line | end$ |
Lines ending with “end” |
\ |
Escape special character | \. |
Literal period |
D.2 Character Classes
| Pattern | Meaning | Equivalent |
|---|---|---|
[abc] |
Any of a, b, or c | — |
[a-z] |
Any lowercase letter | — |
[A-Z] |
Any uppercase letter | — |
[0-9] |
Any digit | \d |
[a-zA-Z] |
Any letter | — |
[a-zA-Z0-9] |
Any alphanumeric | \w (includes _) |
[^abc] |
Any character except a, b, c | — |
[^0-9] |
Any non-digit | \D |
D.3 POSIX Character Classes
| Class | Meaning | Equivalent |
|---|---|---|
[:alnum:] |
Alphanumeric | [a-zA-Z0-9] |
[:alpha:] |
Alphabetic | [a-zA-Z] |
[:digit:] |
Digits | [0-9] |
[:lower:] |
Lowercase letters | [a-z] |
[:upper:] |
Uppercase letters | [A-Z] |
[:space:] |
Whitespace | [ \t\n\r\f\v] |
[:blank:] |
Space and tab | [ \t] |
[:punct:] |
Punctuation | — |
[:print:] |
Printable characters | — |
[:graph:] |
Visible characters | — |
[:cntrl:] |
Control characters | — |
[:xdigit:] |
Hexadecimal digits | [0-9A-Fa-f] |
Note
POSIX classes must be used inside brackets: [[:digit:]] not [:digit:]
D.4 Shorthand Character Classes
| Pattern | Meaning | Equivalent |
|---|---|---|
\d |
Digit | [0-9] |
\D |
Non-digit | [^0-9] |
\w |
Word character | [a-zA-Z0-9_] |
\W |
Non-word character | [^a-zA-Z0-9_] |
\s |
Whitespace | [ \t\n\r\f] |
\S |
Non-whitespace | [^ \t\n\r\f] |
\b |
Word boundary | — |
\B |
Non-word boundary | — |
Warning
Not all tools support \d, \w, \s shorthand. POSIX classes are more portable.
D.5 Quantifiers
| Pattern | Meaning | Example | Matches |
|---|---|---|---|
* |
0 or more | a* |
““,”a”, “aa”, “aaa” |
+ |
1 or more | a+ |
“a”, “aa”, “aaa” |
? |
0 or 1 | a? |
““,”a” |
{n} |
Exactly n | a{3} |
“aaa” |
{n,} |
n or more | a{2,} |
“aa”, “aaa”, “aaaa” |
{n,m} |
Between n and m | a{2,4} |
“aa”, “aaa”, “aaaa” |
{,m} |
At most m | a{,3} |
““,”a”, “aa”, “aaa” |
Greedy vs. Lazy Quantifiers
| Greedy | Lazy | Meaning |
|---|---|---|
* |
*? |
0 or more (prefer fewer) |
+ |
+? |
1 or more (prefer fewer) |
? |
?? |
0 or 1 (prefer 0) |
{n,m} |
{n,m}? |
n to m (prefer fewer) |
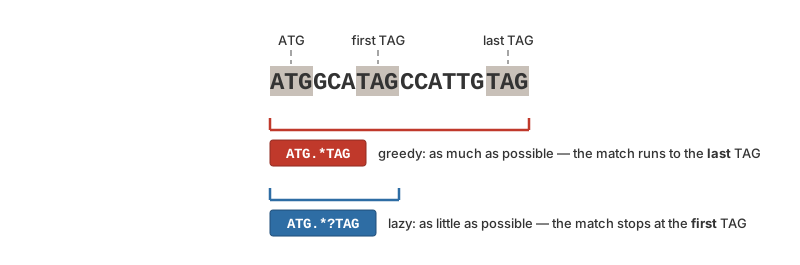
ATG.*TAG expands the match to the last TAG, while ATG.*?TAG stops at the first.
D.6 Anchors and Boundaries
| Pattern | Meaning | Example |
|---|---|---|
^ |
Start of line | ^Start |
$ |
End of line | end$ |
\b |
Word boundary | \bword\b |
\B |
Non-word boundary | \Bword |
\A |
Start of string | — |
\Z |
End of string | — |
D.7 Grouping and Capturing
| Pattern | Meaning | Example |
|---|---|---|
(...) |
Capture group | (abc)+ |
(?:...) |
Non-capturing group | (?:abc)+ |
\1, \2 |
Back-reference | (\w+) \1 matches repeated words |
(?P<name>...) |
Named group (Python) | (?P<word>\w+) |
D.8 Alternation
| Pattern | Meaning | Example | Matches |
|---|---|---|---|
a\|b |
a or b | cat\|dog |
“cat” or “dog” |
(a\|b)c |
(a or b) followed by c | (gray\|grey) |
“gray” or “grey” |
D.9 Lookahead and Lookbehind
| Pattern | Name | Meaning |
|---|---|---|
(?=...) |
Positive lookahead | Followed by … |
(?!...) |
Negative lookahead | Not followed by … |
(?<=...) |
Positive lookbehind | Preceded by … |
(?<!...) |
Negative lookbehind | Not preceded by … |
Lookaround Examples
| Pattern | Matches |
|---|---|
foo(?=bar) |
“foo” only if followed by “bar” |
foo(?!bar) |
“foo” only if NOT followed by “bar” |
(?<=foo)bar |
“bar” only if preceded by “foo” |
(?<!foo)bar |
“bar” only if NOT preceded by “foo” |
D.10 Common Patterns
Numbers
| Pattern | Matches |
|---|---|
[0-9]+ |
Integer |
-?[0-9]+ |
Integer (with optional negative) |
[0-9]+\.[0-9]+ |
Decimal number |
-?[0-9]*\.?[0-9]+ |
Any number |
[0-9]+(\.[0-9]+)?([eE][+-]?[0-9]+)? |
Scientific notation |
Text Patterns
| Pattern | Matches |
|---|---|
\b[A-Z][a-z]*\b |
Capitalized word |
\b[A-Z]+\b |
All caps word |
[A-Za-z0-9._%+-]+@[A-Za-z0-9.-]+\.[A-Za-z]{2,} |
Email (simple) |
https?://[^\s]+ |
URL (simple) |
\b\d{3}[-.]?\d{3}[-.]?\d{4}\b |
US phone number |
Bioinformatics Patterns
| Pattern | Matches |
|---|---|
^>.* |
FASTA header |
^[ACGT]+$ |
DNA sequence (strict) |
^[ACGTN]+$ |
DNA with N |
^[ACGU]+$ |
RNA sequence |
ATG([ACGT]{3})*?(TAA\|TAG\|TGA) |
Open reading frame |
[ACDEFGHIKLMNPQRSTVWY]+ |
Protein sequence |
chr[0-9XYM]+:[0-9]+-[0-9]+ |
Genomic coordinates |
D.11 Tool-Specific Notes
grep Variants
| Command | Regex Type | Notes |
|---|---|---|
grep |
Basic (BRE) | Escape +, ?, \|, {} |
grep -E |
Extended (ERE) | +, ?, \| work without escape |
grep -P |
Perl (PCRE) | Full Perl regex support |
egrep |
Extended (ERE) | Same as grep -E |
Basic vs. Extended Regex
| Feature | Basic (BRE) | Extended (ERE) |
|---|---|---|
| One or more | \+ |
+ |
| Zero or one | \? |
? |
| Alternation | \\| |
\| |
| Grouping | \(\) |
() |
| Repetition | \{n,m\} |
{n,m} |
sed Patterns
awk Patterns
R Regular Expressions
# Base R functions
grep("pattern", x)           # Return indices
grepl("pattern", x)          # Return TRUE/FALSE
sub("old", "new", x)         # Replace first
gsub("old", "new", x)        # Replace all
regmatches(x, regexpr(...))  # Extract match

# stringr functions (tidyverse)
str_detect(x, "pattern")     # TRUE/FALSE
str_extract(x, "pattern")    # Extract match
str_replace(x, "old", "new") # Replace first
str_replace_all(x, "old", "new")  # Replace all
str_split(x, "pattern")      # Split string
D.12 Regex Flags/Modifiers
| Flag | Meaning | Usage |
|---|---|---|
i |
Case insensitive | grep -i, (?i) |
g |
Global (all matches) | s/old/new/g |
m |
Multiline mode | (?m) |
s |
Single-line (dot matches newline) | (?s) |
x |
Extended (allow whitespace/comments) | (?x) |
D.13 Escaping Special Characters
Characters that need escaping in regex:
. * + ? ^ $ { } [ ] ( ) | \To match these literally, precede with backslash:
| To Match | Use |
|---|---|
. |
\. |
* |
\* |
? |
\? |
[ |
\[ |
] |
\] |
( |
\( |
) |
\) |
{ |
\{ |
} |
\} |
\| |
\\| |
\ |
\\ |
^ |
\^ |
$ |
\$ |